Structured Data Extraction With AI That “Can’t Hallucinate”
How AI decision models offer a fast and cost-effective approach to turning unstructured text into decisions Most of the organizational data is unstructured, such as incident reports, support tickets, maintenance logs, call-center transcripts, and customer reviews.
- AI
- Governance
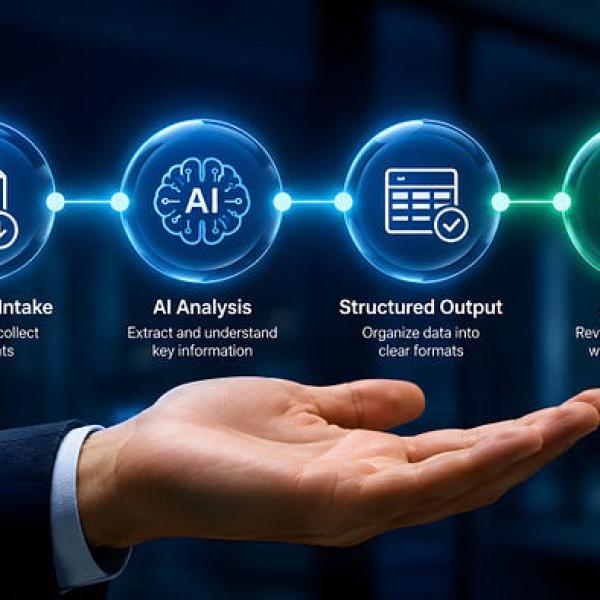
The article explains why large language models are often an inefficient, high-latency, and sometimes unreliable way to perform “structured decision” extraction (like classification, routing, and scoring) and frames a better alternative: specialized decision models that output calibrated probabilities over predefined answer spaces. Using TypeSafe AI’s Jev as an example, it describes how decision models operate on a provided “state” plus “questions,” returning typed outputs (Choice, Score, Noul) with probabilities—preventing invalid answers (“can’t hallucinate”) while still requiring thresholding and validation to manage uncertainty. It also covers how to integrate decision models into real workflows (routing high-confidence cases automatically, escalating uncertain or high-severity cases) and where they fit in the AI stack: as a specialized component that complements LLMs and other extraction methods, especially when values can be represented as constrained candidates rather than fully open-ended text.